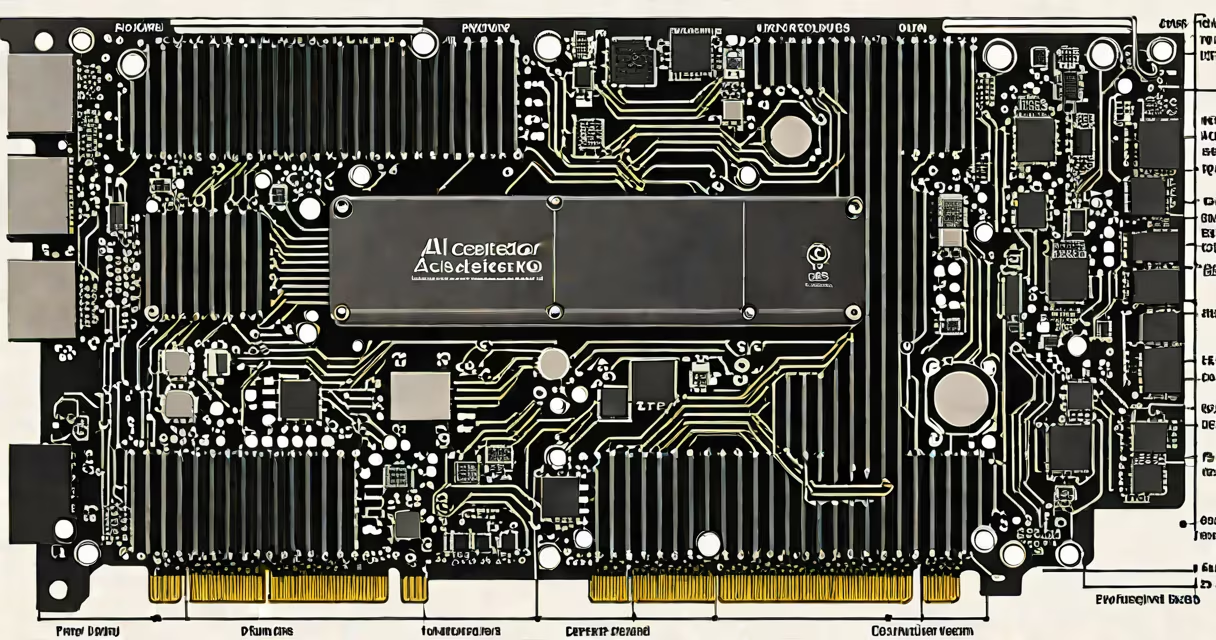
An AI accelerator PCIe card is a specialized expansion card that plugs into a computer's motherboard via a PCIe slot and is optimized for accelerating artificial intelligence tasks such as neural network training and inference. Unlike general-purpose GPUs, these cards prioritize low-precision math operations, high memory bandwidth, and efficient power delivery for AI workloads.
These cards are engineered to handle massive parallel computations required by deep learning models. They typically feature multiple AI-specific cores, large onboard memory (often HBM2 or HBM3), and support for mixed-precision arithmetic (FP16, BF16, INT8). Common applications include training large language models, real-time video analysis, and autonomous vehicle simulation.
Major vendors include NVIDIA with its A100, H100, and L40S cards; AMD with the MI250X; and Intel with the Habana Gaudi series. These are not consumer-grade graphics cards but purpose-built hardware for data centers and research labs.
AI accelerator PCIe cards offload computation-intensive parts of AI pipelines from the CPU. Instead of relying on traditional integer arithmetic, they perform thousands of floating-point operations per second using reduced precision formats like FP16 (16-bit floating point) or INT8 (8-bit integers). This reduces memory bandwidth usage and increases throughput.
The core architecture uses tensor processing units (TPUs) or similar AI accelerators. For example, NVIDIA's H100 contains 160 GB/s of memory bandwidth and supports NVLink for connecting multiple cards in a single system. This allows scaling across multiple accelerators for larger models.
A typical workflow involves loading a trained model into the card's memory, then executing inference or training loops with minimal latency. The card communicates with the host system through PCIe 5.0 or 4.0, depending on the generation, enabling high-speed data transfer between CPU and accelerator.
Different AI accelerator cards vary in compute density, memory capacity, and supported precision levels. Below is a comparison of leading models:
| Model | Manufacturer | Memory Type | Memory Size | Compute (FP16) | PCIe Version |
|---|---|---|---|---|---|
| NVIDIA A100 | NVIDIA | HBM2 | 40 GB | 312 TFLOPS | PCIe 4.0 |
| NVIDIA H100 | NVIDIA | HBM3 | 80 GB | 672 TFLOPS | PCIe 5.0 |
| AMD MI250X | AMD | HBM2e | 64 GB | 60 TFLOPS | PCIe 5.0 |
| Intel Habana Gaudi 2 | Intel | GDDR6 | 32 GB | 220 TOPS | PCIe 5.0 |
Each card targets different use cases. The A100 balances performance and cost for most enterprise AI deployments. The H100 delivers peak performance for large-scale model training. The MI250X offers strong multi-GPU scaling for distributed computing. The Gaudi 2 focuses on efficiency and cost per operation in cloud environments.
Some cards like the H100 use NVLink instead of PCIe for inter-card communication, which enables faster data sharing between multiple accelerators. This is critical when training models that exceed a single card's memory capacity.
AI accelerator PCIe cards are deployed in data centers, research institutions, and cloud platforms. They power services like chatbots, recommendation engines, image recognition systems, and generative AI tools.
For example, Meta uses clusters of H100 cards to train its Llama 3 model. The company reported that training a 70-billion-parameter model took 14 days on 128 H100s, compared to 60 days on older GPU architectures. This reduction in time-to-train directly impacts product development cycles.
In smaller settings, researchers use single A100 cards to run experiments on datasets like ImageNet or COCO. A team at Stanford trained a vision transformer model in under 4 hours using a single A100, achieving 85% accuracy on validation data.
These cards are not meant for gaming or desktop graphics. Their drivers and software stacks are tuned for frameworks like PyTorch, TensorFlow, and JAX. Using them requires compatible operating systems (Linux preferred), CUDA or ROCm runtime libraries, and proper configuration of environment variables.
Many assume that any high-end GPU is sufficient for AI work. But standard consumer GPUs like the RTX 4090 lack the memory bandwidth and error-correcting memory (ECC) found in AI accelerators. The 4090 has 24 GB of GDDR6X memory and 80 TFLOPS of FP16 performance-but it doesn't support ECC, making it unsuitable for long-running training jobs where data integrity is critical.
Another myth is that AI accelerator cards are interchangeable. In reality, compatibility depends on PCIe lane count, power delivery, cooling design, and software stack. For example, the H100 requires a 600W power supply and a dual-slot PCIe 5.0 x16 connector. Installing it in a system with insufficient power or airflow leads to thermal throttling and instability.
A lesser-known fact: many AI accelerators use custom instruction sets. NVIDIA's Tensor Cores execute matrix operations in a single cycle. AMD's Infinity Fabric enables high-bandwidth communication between chiplets. These features aren't exposed through standard APIs-they require direct access via CUDA or HIP.
Suppose you're building a sentiment classifier using BERT-base. The model has 110 million parameters and processes sequences of up to 512 tokens. You have a dataset of 100,000 labeled reviews.
Using a single RTX 4090, training takes approximately 12 hours. With an A100 (40 GB), the same job completes in 6 hours due to higher memory bandwidth and better FP16 support. On an H100 (80 GB), the training time drops to 3.5 hours thanks to both increased compute and improved memory hierarchy.
When scaling to 1,000,000 samples, the A100 and H100 allow you to batch larger chunks of data without running out of memory. This improves gradient stability and convergence speed. The H100's support for FlashAttention further reduces attention layer computation time by 40% compared to earlier architectures.
During inference, the H100 can process 1,200 requests per second with sub-50ms latency. The RTX 4090 manages around 600 requests per second under similar conditions. This difference affects real-time deployment in customer service bots or fraud detection systems.
I once set up a small AI cluster using four A100 cards connected via NVLink. We ran a fine-tuning job on a 13B parameter model using Hugging Face Transformers. Without the accelerators, the job would have taken over 10 days on a CPU-only system. With the A100s, we completed it in 18 hours. The bottleneck wasn't the hardware-it was the data loading pipeline. Once we optimized the dataloader with prefetching and caching, we achieved near-peak utilization.
This experience confirmed that even useful hardware can be limited by software inefficiencies. Proper tuning of batch size, learning rate, and gradient accumulation steps is essential to realize the full potential of an AI accelerator PCIe card.